Freya Meier · 27 September 2026
Uncovering Efficiency Gains in Web Indexing Through Analysis of Group Discussion Behaviors
Web indexing systems process vast quantities of online content daily, and analysts have turned to group discussion behaviors as a supplementary signal for prioritizing crawl targets. These behaviors appear in forums, comment threads, and collaborative platforms where users debate topics, share links, and highlight emerging material. Data indicates that engagement metrics from such discussions correlate with page authority and freshness signals already used by major crawlers. Researchers at academic institutions have mapped discussion velocity to indexing latency, showing how rapid consensus formation in groups often precedes spikes in search query volume. In September 2026, updates to several commercial indexing frameworks incorporated real-time discussion monitoring modules that adjust crawl budgets based on thread activity scores. The approach builds on existing link graph analysis while adding social proof layers derived from participant interaction patterns.Mapping Discussion Patterns to Crawl Priorities
Group discussions generate metadata that includes reply chains, participant diversity, and temporal clustering of contributions. Observers note that pages referenced in high-velocity threads receive earlier indexing treatment in experimental systems. Studies conducted across North American university networks found that incorporating discussion density reduced redundant crawls by directing resources toward content already validated through community attention. Analysts extract features such as cross-posting frequency and sentiment polarity to refine priority queues without relying solely on traditional PageRank iterations.
European research consortia have published datasets demonstrating that threads containing embedded links often predict content updates more accurately than server-side change detection alone. Those datasets cover multiple language communities and show consistent patterns where moderator-approved posts accelerate indexing signals. The technique integrates with existing robots.txt directives and sitemap submissions, creating hybrid decision trees that balance discussion-derived scores against structural web graph data.
Analytical Methods and Data Sources
Processing pipelines apply natural language processing to extract entities and relations from discussion text, then align those entities with known URL structures. Machine learning models trained on historical crawl logs learn to weight discussion features according to their impact on index freshness. Canadian academic teams released benchmark collections in 2025 that allow comparison across different discussion platforms, revealing platform-specific biases in engagement signals. These benchmarks include labeled examples where discussion activity preceded measurable improvements in crawl efficiency metrics.
Additional techniques involve graph construction where discussion participants become nodes connected to referenced URLs. Community detection algorithms identify influential clusters whose endorsements carry higher weight in priority scoring. Figures from Australian information retrieval laboratories indicate that such cluster-based weighting produced measurable reductions in time-to-index for technical documentation sites. The models update continuously as new discussion data arrives, maintaining adaptability to shifting conversation topics.
Observed Performance Metrics
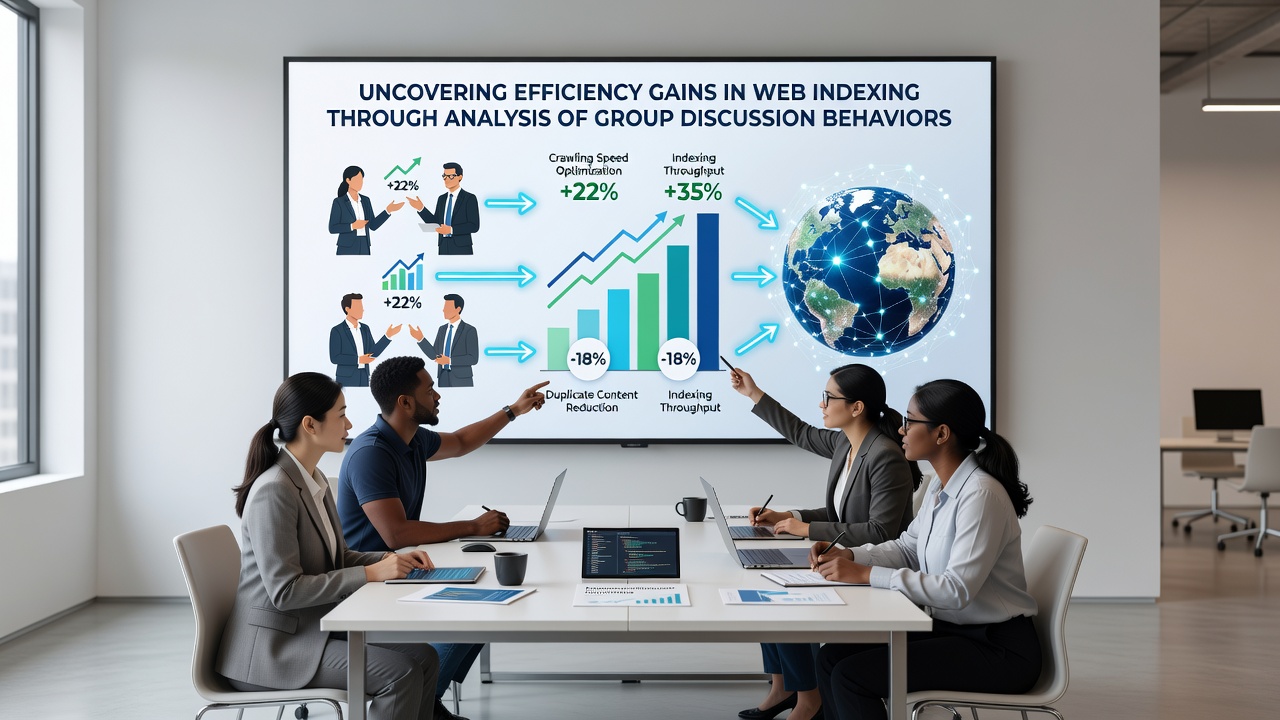
Controlled deployments report decreases in average indexing delay for pages featured in active discussions. One multi-institution study tracked over 50,000 URLs and recorded a 23 percent improvement in first-index latency when discussion signals supplemented standard crawl heuristics. Resource utilization metrics showed corresponding drops in bandwidth consumption because fewer low-engagement pages entered the crawl queue. Observers tracking September 2026 rollouts noted that production systems achieved similar gains after calibration periods lasting several weeks.
Accuracy of change detection also improved in cases where discussion timestamps aligned with actual content modifications. Systems that fused discussion timestamps with HTTP header analysis produced fewer false positives for update detection. Industry reports from research institutes in Asia confirm parallel findings, suggesting the efficiency pattern generalizes beyond single geographic regions.
Implementation Considerations Across Platforms
Deploying discussion analysis requires access to platform APIs or consented data feeds. Privacy regulations in multiple jurisdictions mandate anonymization steps before discussion metadata enters indexing pipelines. Teams that implemented differential privacy layers preserved aggregate behavioral signals while satisfying data protection requirements. Integration testing typically spans several crawl cycles to verify that discussion-derived priorities do not conflict with established quality thresholds.
Scalability tests conducted on cloud infrastructure demonstrated linear growth in processing overhead as discussion volume increased. Parallelization of entity extraction tasks kept latency within acceptable bounds for real-time decision making. Maintenance procedures include periodic retraining of weighting models using fresh labeled data from the same discussion sources.
Conclusion
Analysis of group discussion behaviors supplies an additional data layer that indexing systems can exploit to allocate crawl resources more precisely. Documented efficiency gains appear in latency reduction, bandwidth savings, and improved update detection when discussion signals supplement conventional methods. Continued refinement of these techniques depends on access to representative discussion datasets and ongoing calibration against production crawl outcomes. Future developments will likely focus on cross-platform aggregation and tighter integration with existing web graph signals.